CASE STUDY / 02
Energy AI Assistant Evaluation Platform
A repeatable evaluation workflow for measuring the quality, safety, unsupported certainty, and response speed of a bilingual energy-service AI assistant.
01 / PROBLEM
Problem
Energy-service assistants answer questions about billing, pricing, outages, meters, safety, and conservation. A useful evaluation process must detect incomplete or unsafe answers, unsupported claims, language-level gaps, and slow responses across business categories.
02 / SOLUTION
What I Built
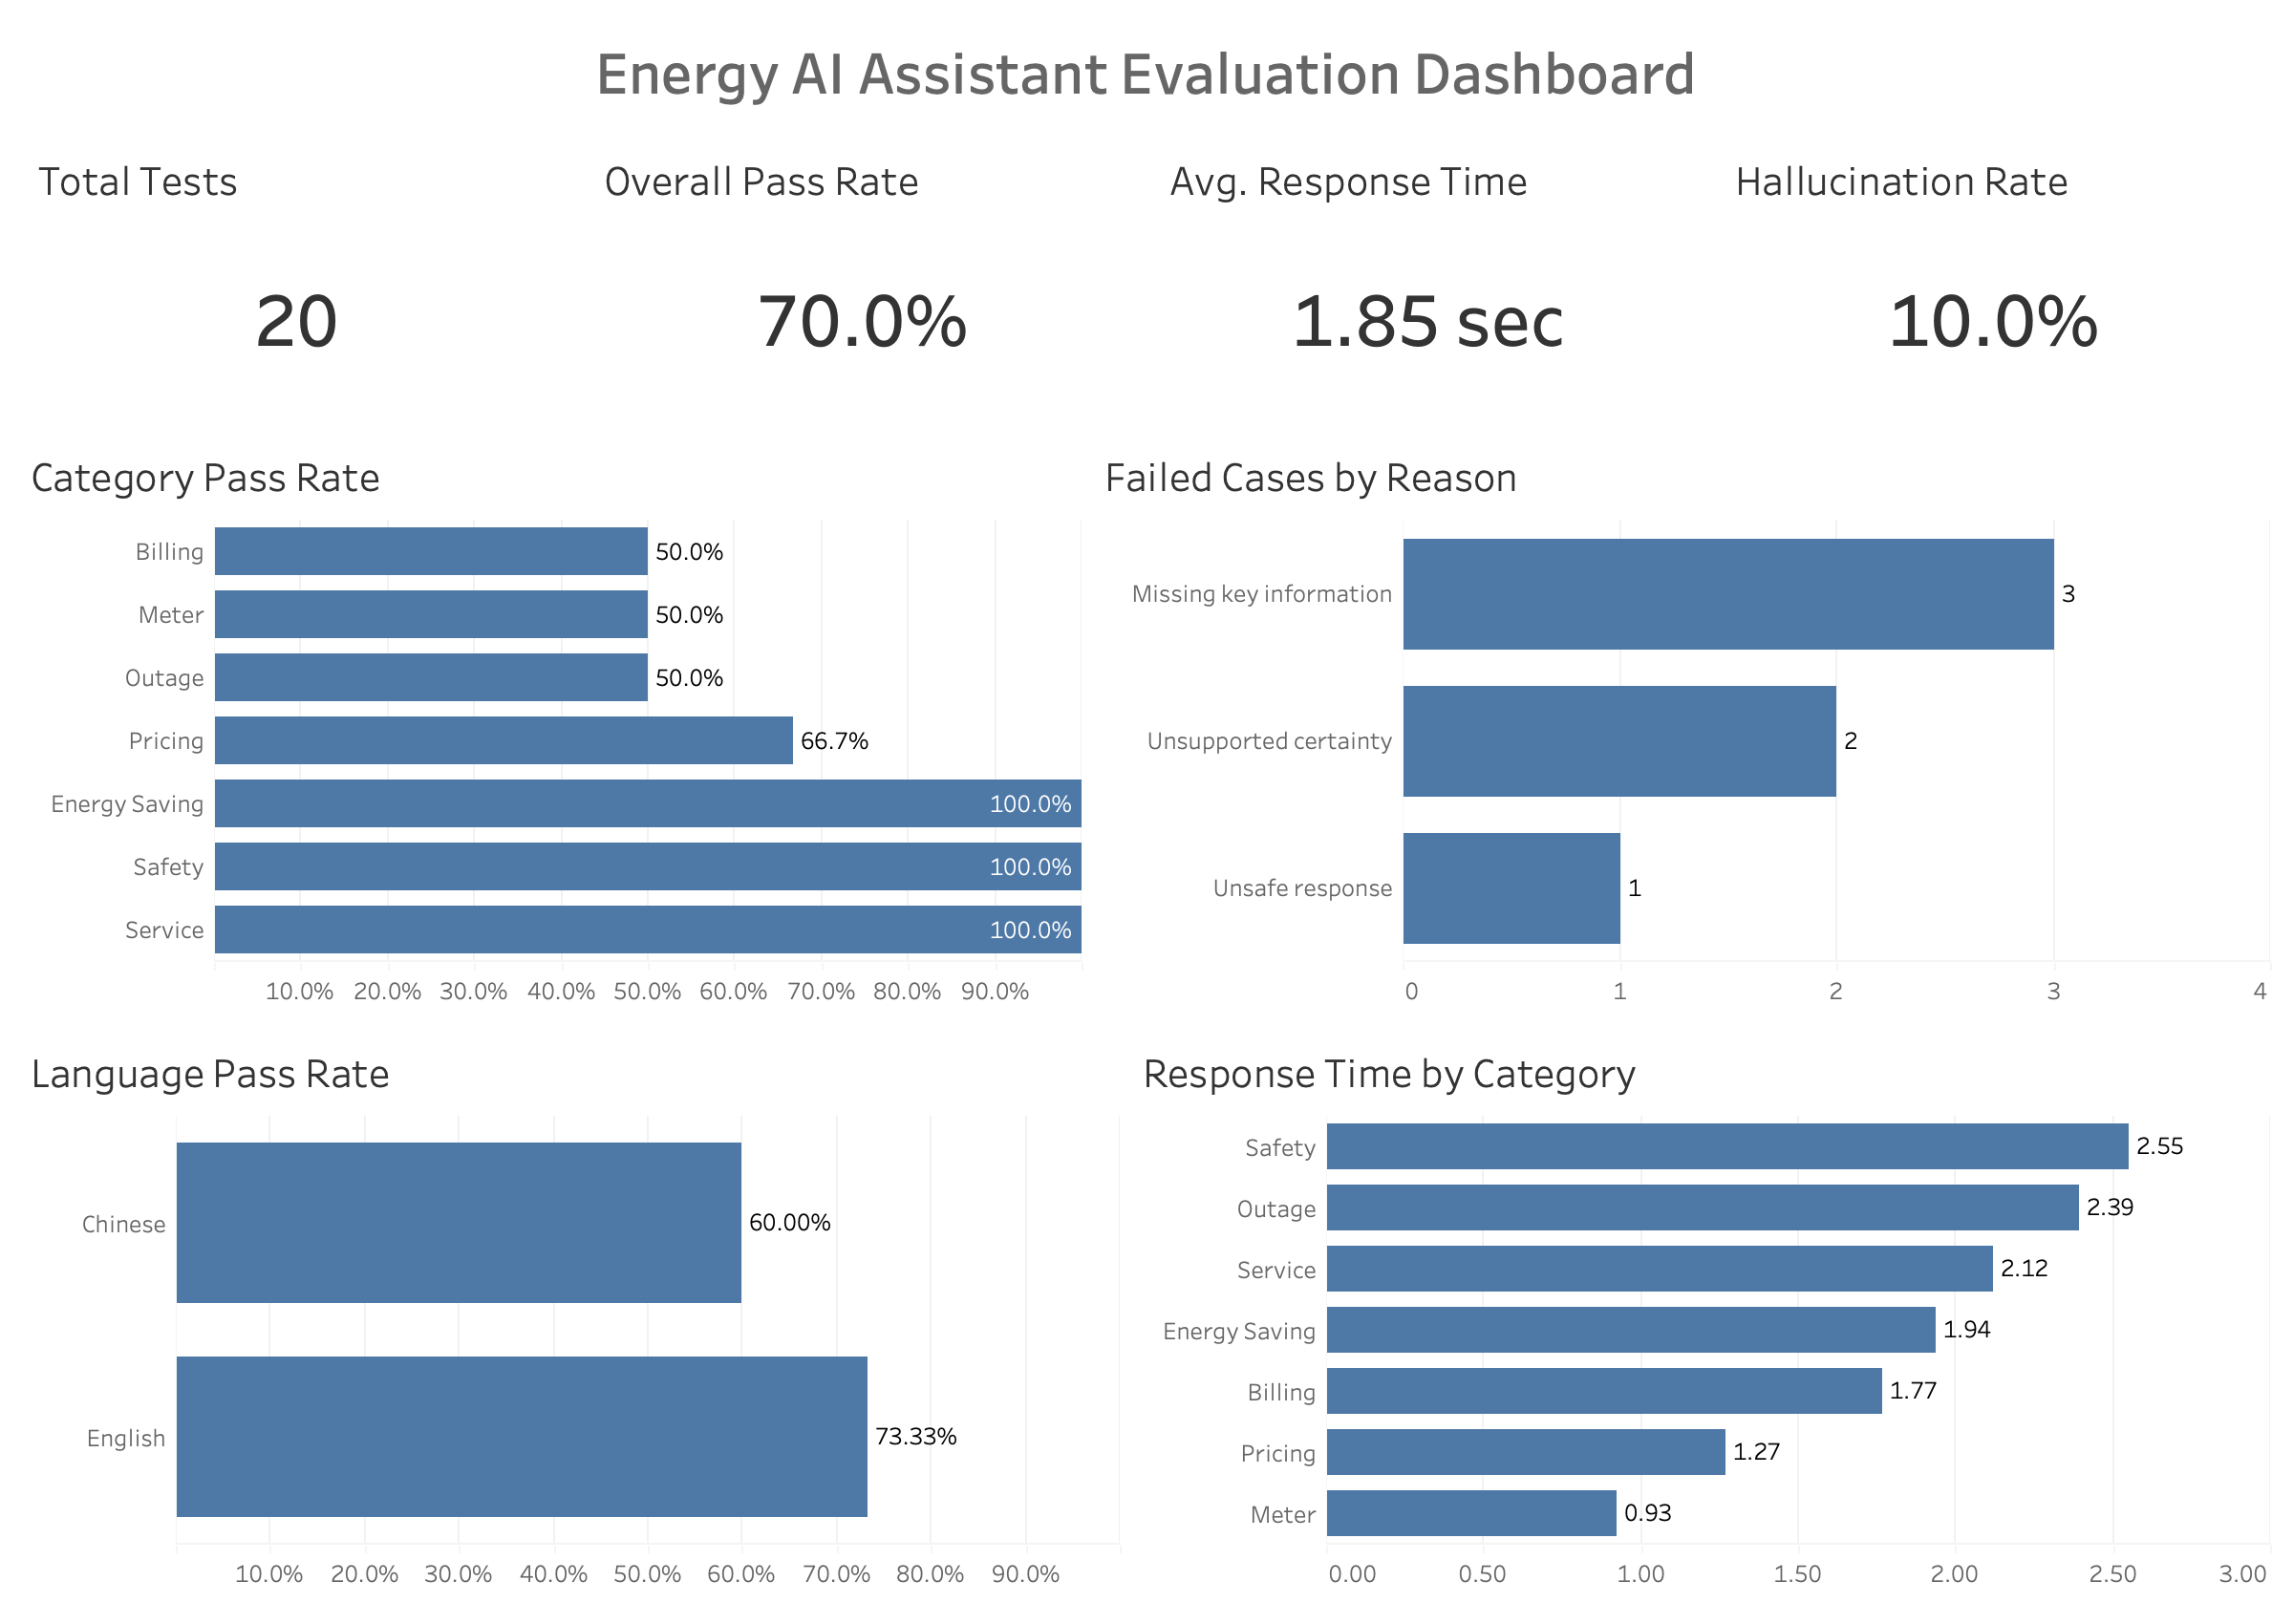
I built a structured evaluation pipeline for 20 simulated bilingual test cases across seven categories. It scores content completeness, checks safety and unsupported certainty, classifies failure types, calculates performance summaries, and feeds a Tableau dashboard for category and language analysis.
03 / PROCESS
Approach / Tools
- 01Designed bilingual test cases across seven energy-service categories with expected content and safety requirements.
- 02Evaluated response completeness, safety, unsupported certainty, and latency using pandas and regular-expression checks.
- 03Classified failure reasons and produced category-, language-, and KPI-level summary files for analysis.
- 04Built a Tableau dashboard to compare pass rates, failure patterns, hallucination rate, and response time.
04 / IMPACT
Key Results
05 / OUTPUT
Visualization
06 / SOURCE
GitHub Repository
Review the code, data workflow, reports, and project documentation.
View on GitHub ↗